Showing posts with label yDNA. Show all posts

Wednesday, January 28, 2015

Ghosts of DNA Past: Irish Kings

   In 2006, Laoise T. Moore and the folks at Trinity College in Dublin published a paper famous for identifying the modal haplotype of Irish High King Niall of the Nine Hostages.  In their work, they used seventeen Y-DNA STR markers.  While time to most recent common ancestor (TMRCA) calculations have accuracy issues, having only 17 markers gives a common ancestor over 2,000 years ago.   What the Trinity folks really accomplished was the identification of Niall’s paternal ancestor from over 400 years earlier.  The media in 2006 had a field day in their interpretation that most of Ireland is descended from Niall.  “Niall may be the most prolific male in Irish history.”  Also at 17 markers, there is a very high probability of convergence.  Through normal mutations, haplotypes can change over time to appear similar or identical to other haplotypes.  The lower the number of markers, the higher the chance of convergence.  At that time only high level SNPs were tested to determine haplogroup.  Without terminal SNPs it would have been impossible to recognize convergence, if it existed in the samples.

   In my research on the Kings of Ireland, I have used 67 markers to reduce the chance of convergence and to calculate the age of common ancestors on the descendant side of the target rather than the ancestor side.  I will demonstrate traditional median-joining networks and novel “tribal” markers for the identification of four historic Kings of Ireland.  Did Trinity get Niall’s haplotype correct with the limited data they had at the time?

Ghost:  a manifestation of a dead person

Modal haplotype:  a derived haplotype based on the DNA tests of a group of people

   A modal haplotype is a ghost of a person.  When we look at multiple DNA test results and calculate the mode, by definition we are just taking the values that appear most often.  There is no way to determine if the modal haplotype is the actual haplotype of the historic individual we are researching (short of historic samples).  While the modal is not perfect, it will be close enough at 67 markers for us to determine the genetic “ghost”.

   The septs of Ireland provide us an opportunity to develop genetic genealogy techniques and processes.  Irish surnames are typically patronymic.  The surnames generally take the form of Mac Cárthaigh (McCarthy), meaning son of Cárthaigh or Ui Néill (O’Neill), meaning grandson / descendant of Néill.  Irish septs serve as a collective of related families with shared ancestry and patronymic surnames.  Multiple septs then belong to larger dynasties such as the Eóganachta and the Dál gCais.

   If septs are patrilineal, then Y-DNA haplotypes should be consistent across sept surnames.  Research on the Uí Néill haplotype started with a geographical selection and then a subsequent reduction by sept surnames (Moore et al 2006).  For each target sept, affiliated surnames were identified.  In the case of Uí Néill, the following surnames and associated Y-DNA STR records were accessed from Family Tree DNA projects: O’Neill, Gallagher, Doherty and O’Donnell.  The selection includes 600 records and 5 common European haplogroups.

   Median-joining networks have been in use for over a decade for the visualization of genetic relationships.  The use of them at 67 STR markers has been rare, but it should be the norm.  This first image has the central cluster of a median joining network based on 25 STR markers from the Uí Néill group.  It is just a single cluster with no differentiation.


Figure 1 - Using only 25 STR markers, the Uí Néill network collapses to a single cluster.

When we look at the same group using 67 markers, we get four distinct clusters, each with their own SNP.  The cluster at the far right is predominantly R-L159 and the cluster at the lower right has R-P311/R-L151 nodes.  The cluster at the left contains all of the Uí Néill dynastic surnames, has the majority of nodes and is SNP R-M222, which is consistent with earlier studies.


Figure 2 - View of the Uí Néill network torso showing four distinct clusters.  Three groups on the right are O’Neill only.

As a double check to make sure that I wasn’t seeing some other phenomena, I analyzed three random Irish surnames; Duffy, Kelly and McCormick.  The random sample produced over ten unique clusters with no surname overlap.  This comparison shows that septs are patrilineal and that Y-DNA haplotypes are consistent across sept surnames. 

Figure 3 - Median-joining network of yDNA sampled from three random Irish surnames; Duffy, Kelly and McCormick.  

Re-evaluating the Uí Néill data also shows that Trinity was correct in their identification of a 17-marker Uí Néill haplotype.  New data and new techniques allow us to produce a 67-marker haplotype.


Figure 4 - Sixty-seven STR Uí Néill Modal Haplotype (Niall of the Nine Hostages).

   A different technique that I’d like to illustrate involves the fact that not all STR markers are created equal.  This method takes advantage of “slow” mutating STR markers.  Each marker has its own mutation rate.  By selecting the 15 “slowest” markers with an average mutation rate of 0.00024, a virtual tribal haplotype is created that would be stable within the last 2,000 years (90% probability of 80 generations).  This is an order of magnitude lower than the average rate of 0.0029 used as a constant in typical TMRCA calculations.  The “tribal” markers isolated are DYS426, DYS388, DYS392, DYS455, DYS454, DYS578, DYS590, DYS641, DYS472, DYS594, DYS436, DYS490, DYS450 and DYS640.

   To manipulate the “tribal” haplotype of 15 microsatellites faster the resulting values are concatenated into a string – ex. 12121411119168108101212811.  The “tribal” haplotypes are summarized per surname and plotted to illustrate majority and affinity.


Figure 5 - Uí Néill dynastic haplotypes converted into 15 marker “tribal” haplotypes and summarized.

   The Uí Néill dataset resolved into 37 unique “tribal” haplotypes.  Figure 5 shows that haplotype 12121411119168108101212811 is the most dominant across the Uí Néill surnames.  As with the median-joining network analysis, this “tribal” haplotype is consistent with SNP R-M222. 

   I repeated these two techniques for the Uí Briúin sept using the following surnames and associated Y-DNA records: O’Brien, Hogan, Kennedy and McMahon.  The selection includes 615 records.  The Mac Cárthaigh dataset has the following surnames: McCarthy, Callaghan, Donovan and Sullivan.  The selection includes 319 records.  The Ua Conchobhair data has the following surnames: O’Connor, McManus, Reilly and Rourke.  The selection includes 352 records.

For more details, see my paper at Academia.edu.


Figure 6 - Sixty-seven STR Uí Briúin Modal Haplotype (Brian Boru).


Figure 7 - Sixty-seven STR Mac Cárthaigh Modal Haplotype (McCarthy Eoganachta Kings).


Figure 8 - Sixty-seven STR Ua Conchobhair Modal Haplotype (Last High King Roderick O'Connor).


   Here are a couple of interesting insights from my research.  Niall Noígíallach was High King of Ireland around 378 CE and founder of the Uí Néill dynasty.  Historically, his half-brother Brión, was one of the founders on the Connachta dynasty and an ancestor of the last High King of Ireland, Ruaidrí Ua Conchobair.  If their genealogies are correct, the evidence is in their descendant’s DNA.  The data shows that Uí Néill and Ua Conchobair share the same SNP, R-M222.  The Uí Néill and Ua Conchobair modals are a 6-step match at 67 markers.  There is a 99% probability of a relationship not further than 1,260 years ago.  The results make a strong case for the validity of this historic genealogy.

   Brian Boru, High King of Ireland in 1002 CE, belonged to the Dál gCais dynasty and Tadhg Mac Cárthaigh, the first King of Desmond, belonged to the Eóganachta dynasty.  Ancient genealogies have the Eóganachta and Dál gCais dynasties descended from Ailill Aulom, the son-in-law of legendary king Conn of the Hundred Battles.  The Mac Cárthaighs and Uí Briúins do not share the same SNP (R-L226 vs. R-CTS4466), but by descent they would share a common R-DF13 ancestor.  The Mac Cárthaigh and Uí Briúin modals are an 11-step match at 67 markers.  There is a 99% probability of a relationship not further than 1,920 years ago.  This puts a Mac Cárthaigh-Uí Briúin common ancestor as a contemporary of the legendary Conn.

   New and improved genetic genealogy techniques are invaluable for the identification of historic individuals and the reconstruction of distant family trees at the macro level.

Reference:


Maglio, MR (2015) Identifying Y-Chromosome Dynastic Haplotypes: The High Kings of Ireland Revisited (Link)

Friday, December 5, 2014

DNA Convergence and Chicken Little

   For me, the topic of convergence in yDNA first came up early in 2014.  I had just posted a paper and one of the comments was – “What about convergence?”  I said to myself, “What convergence?”  I admit I had to look up the topic.

Convergence: A term used in genetic genealogy to describe the process whereby two different haplotypes mutate over time to become identical or near identical resulting in an accidental or coincidental match. - Turner A & Smolenyak M 2004.

My response back to the comment was - “All of the haplotypes in my paper are unique.”  My data did not exhibit convergence. 
Convergence casts a shadow on genetic genealogy
   I started to poke around on the topic of convergence within yDNA STR haplotypes and the immediate impression that I got was that folks were ready to give up on STRs in favor of SNPs and the sky was falling.  Chicken Little was running around in the genetic genealogy circles.  Here is a small sample:

“Y-STRs are effectively dead” - Dienekes Pontikos, 2011

“Convergence of Y chromosome STR haplotypes from different SNP haplogroups compromises accuracy of haplogroup prediction” – Wang, et al, 2013

   Okay, convergence happens, but it’s an illusion.

   Let’s take a big step backwards in this story.  Did you know that most scientific papers relating to genetic genealogy use 17 STR markers or less?  Some use as few as 9 or 10.  For any of you who ever took one of the original 12 STR marker tests, you know that the results were essentially useless for anything except deep haplogroup association and history.

   Many researchers in the last couple of years are using the AmpFLSTR® Yfiler® to get their 17 marker results.  This equipment is approved for forensic cases.  Research papers are not forensic cases and researchers don’t need to limit themselves to 17 markers.  Thirty-seven marker yDNA tests have been available since 2004.

   Why does the number of STR markers matter?  I’m going to release my inner math geek to help explain.  If we look at marker DYS19, usually listed first in science papers and third in Family Tree DNA results, it can have a value within the range of 7 to 22 across all haplogroups.  Looking at R1b specifically, DYS19 ranges from 10 to 17 and statistically at two standard deviations (2 sigma) the range of values narrows to 13, 14 and 15.  From a probability point of view, there is a 1 in 3 chance that DYS19 will be 13, 14 or 15.  Making the odds even better in our favor, 95% of the time DYS19 for R1b will already be 13, 14 or 15.  This means there is a 1 in 2 chance that DYS19 could change to another value on its way to converging with another haplotype.

   Taking standard deviation into account to determine the possible number of values for the STR markers and then multiplying each probability gives the odds that a haplotype could converge.
STR
DYS393
DYS390
DYS19
DYS391
DYS385a
DYS385b
DYS426
DYS388
DYS439
DYS389i
DYS392
DYS389ii

Total
# of possible
marker values
2
4
2
2
2
4
1
1
2
2
2
2

4096

   There is a 1 in 4096 chance that two R1b 12 marker haplotypes could converge.  This is not the probability that one marker will change.  This is the probability that all 12 markers will change enough to match another haplotype.  These are very good odds and the reason why a 12-marker test is practically useless. 

   With a high probability that 12 STR markers will converge, haplotypes start to blend together.  Two different haplogroups or family lines will appear to be the same.  Converging also means that when we calculate the time to the most recent common ancestor (TMRCA), it will look like less time has passed.  Convergence makes a 12-marker test result unusable for genealogical matching, haplogroup prediction and TMRCA calculations.  The Chicken Littles are correct, we have a problem with 12 marker STR results.

   What about 17 markers, a quasi-industry standard for science papers?  Taking the same approach with statistics and probability, a 17-marker yDNA R1b result has a 1 in 2 million chance of converging with another haplotype.  Each haplogroup has slightly different odds.  There is a 1 in 500,000 chance of an R1a 17 marker haplotype converging.  Those odds are better than any lottery.  Convergence is still a problem at 17 markers.

   When Dienekes Pontikos proclaimed the death of yDNA STRs, he was commenting on the attempt to get good TMRCA dates from 10-marker results.  I agree, you can’t get valid TMRCA dates from 10-markers.  When Wang, et al, determined that convergence compromises haplogroup prediction, they were correct, 17 marker haplotypes can converge to make one haplogroup look like another.

   In a quick analysis of 4,300 unique 37-marker R1b haplotypes, the average genetic distance is 17 steps for 37 markers.  That means there are 17 mutations required for convergence in a 37-marker haplotype.  Nearly half of the markers in the haplotypes would need to change.  When we look at the probability of 25-marker haplotype convergence, the chances are 1 in 84 million.  Considering there are about 3.6 billion men on the planet, one in 84 million is still in the realm of possibility.  By the time we get to 37-markers, the odds are 1 in 49 trillion.

   There is a 1 in 49 trillion chance that all the necessary mutations will occur in order for two 37-marker haplotypes to converge.  The odds are likely much higher.  I’ve only looked at the probable values for each marker and I haven’t taken into account the STR mutation rates, the possibility that a marker will change over time. 

   There is essentially no such thing as convergence when 37 or more markers are tested and researched.  If you eliminate the possibility of convergence by using 37 STR markers, then immediately TMRCA calculation become more accurate and haplotypes from different haplogroups no longer resemble each other.  The reports of the death of yDNA STR results have been greatly exaggerated.


   I can’t tell you why researchers are currently stuck on 17 markers.  I can tell you that any research using less than 37 markers runs the risk of convergence in their data, which in turn could lead to the wrong conclusions.  I still consider genetic genealogy to be in its infancy.  Every month new research papers are published and the new concepts introduced are latched onto immediately.  It is understandable that papers from over a decade ago used a dozen STRs and a handful of SNPs, that was the height of technology.  If the latest technology and best data are not being used in today’s research papers, is that equivalent to scientific negligence?  Or, am I missing something and this is a case of scientific ignorance on my part?

Tuesday, December 2, 2014

DNA, SNP, STR, OMG!

(Originally published May 2014 in Going In-Depth)

   Oh my gosh, there are many acronyms in genetic genealogy.  You have to agree that using the acronym DNA is better than writing deoxyribonucleic acid repeatedly.  Although, when we talk about using DNA for genealogy and we only use acronyms, they start to lose their meaning and become just another ‘thing’.  “Hey, I’ve got a SNP.  Do you have a SNP?”  “I dunno, let me check.”  Maybe I’m weird.  I like to understand what all the acronyms mean and how they play a part in the larger picture.

   Let’s start with some DNA basics.  We have DNA in every cell except the red blood cells.  Inside the nucleus of our cells, we have 46 chromosomes or 23 pairs (nuclear DNA).  One set of 23 comes from dad and one set comes from mom.  If we took the tightly coiled DNA from one cell and stretched it out it would be about six feet long.  In that six-foot double helix from one cell, there are over 3 billion base pairs.  If you picture our double helix DNA as a twisted ladder, each rung is a base pair made up from four nucleotides (DNA building blocks).  The rungs are made from either an adenine-thymine rung or a cytosine-guanine rung.


   When we talk about DNA, we often also talk about mitochondrial DNA.  Mitochondria exist outside of the nucleus as an energy source for the cell and have their own independent DNA.  Mitochondrial DNA has just over 16,000 base pairs in comparison to the 3 billion base pairs in our nuclear DNA.  We inherit our mitochondrial DNA only from our mothers.

   DNA is divided into coding regions (genes that define proteins for such things as eye color) and non-coding regions (sometimes called junk DNA).  The coding region that defines us is less than 2% of our overall DNA and within that, there are less than 25,000 genes.  A gene is a sequence of nucleotides averaging about 23,000 base pairs.  One of the largest genes, which encodes for the Caspr2 protein, has over 2.3 million base pairs.


   Within the 3 billion base pairs of our DNA there are variations (normally occurring mutations), where one base pair has been replaced with another base pair.  As an example, it was adenine (A) and now its guanine (G).  This is a single nucleotide polymorphism or SNP (pronounced snip).  There are over 15 million SNPs in our DNA.  Once a SNP occurs, it is usually permanent in the population.  The farther back in time that the SNP occurred, the more people will have that particular mutation.  To be considered a SNP, it has to exist in greater than 1% of the population.  They are found in both the coding and non-coding regions of our DNA.  In the coding regions, SNPs are often markers for genes.

   Let’s divide our DNA into four groups.  Group one, the autosomes, are the first 22 pairs of chromosomes.  The next two groups, the sex chromosomes, are one X and one Y if you are male and two Xs if you are female.  That gives us yDNA and xDNA.  The last DNA group is mitochondrial.  All types of DNA have SNPs.  Autosomal SNPs are used for health and ethnicity.  Mitochondrial and Y-DNA SNPs are used to determine world haplogroups.  While there are 1,000s of X SNPs, there doesn’t seem to be much research around them.

   SNPs have no effect on health, but their presence may predict a health risk.  If you had an autosomal test from 23andMe (prior to the FDA ruling), they would have delivered health information with your results.  They were able to report SNPs in the coding region associated with gene combinations responsible for health risks, like cancer or Alzheimer’s or basic information, like eye and hair color.  Even though you cannot get health information from 23andMe currently, you can still use your autosomal results with Promethease from SNPedia.com to research your health risks.
   Combinations of SNPs are analyzed to determine ancestry-informative markers (AIM – another new acronym for you).  AIMs are used to estimate the ethnicity or at least the geographic origins of your ancestors.  When you receive ethnicity results from an autosomal test, it will be based on the AIMs that the test company are using.  They don’t all use the same markers, so results will vary.  There are even 42 SNPs associated with having Neandertal ancestry.
   SNPs are used to organize us into larger branches of the human family tree (haplogroups).  Our maternal family tree is organized into 26 branches (A through Z) using mitochondrial DNA.  Our paternal tree is similarly organized into 20 branches (A through T) using yDNA SNPs.   As an example, take four men (I use men because the scenario works for both mitochondrial DNA and yDNA), Abe, Bob, Chaz and Dave.  Test each of them for three SNPs, X, Y and Z.  You find that they all test positive for SNP Z, Abe and Chaz test positive for X and Bob and Dave test positive for Y.  You can start to see the branches and the beginning of a tree.


   The first yDNA and mtDNA trees were built using only a few dozen SNPs.  Today, the paternal and maternal haplogroup trees are much more detailed, based on thousands of SNPs.  Complete SNP testing has been available for mitochondrial DNA for a number of years.  Starting last year, complete SNP testing is available for yDNA from companies like FamilyTreeDNA with their Big Y test.  Previously yDNA SNP tests were designed to look for specific SNPs.  With advances in technology, they can now look for all the SNPs across over 12 million yDNA base pairs.

   Just to add another acronym to the pile, there are also STRs or short tandem repeats (aka microsatellites).  STRs are short sequences of base pairs that repeat.  These repeats are found in autosomal, y and x DNA.  You may have heard the term CODIS if you watch Crime/Drama shows on television.  CODIS is the FBI’s Combined DNA Index System (more acronyms).  When DNA is collected for CODIS, they typically test for 13 STR markers across the autosomes.  When you have a yDNA STR test done, genetic genealogy companies test for up to 111 markers only on the Y chromosome.  They will also perform a basic SNP test to identify your paternal haplogroup.  SNPs and STRs are different in that SNPs appear to be permanent changes in our DNA and STRs are variable.  STRs are identified by location on the chromosome and by the number of times that the repeat occurs.  The number of repeats per STR can change over time, sometimes increasing, sometimes decreasing in number or increasing then decreasing again (known as a back mutation).  The combined set of STR markers is your haplotype and may be unique to your surname or span multiple surnames.  With the advances in yDNA SNP testing, SNPs will be found that are unique to your surname, which could make STR testing obsolete.

   We all have DNA: 23 chromosomes in our cell nuclei, half from mom and half from dad.  We also have mitochondrial DNA from our moms.  Less than 2% of our DNA is in the form of genes, which define who we are.  SNPs can be used to identify our “good” and “bad” genes.  SNPs can also help identify our ethnicity and build our paternal and maternal family trees.  STRs can organize us down to the paternal surname level.  When folks start talking DNA, don’t be afraid to question them about, “What kind of DNA?”, “What does that SNP indicate?” or “What type of STR is being tested?”.  We’ll never get away from using acronyms to simplify how we communicate genetic genealogy.  That doesn’t mean we need to let the acronyms simplify the meanings to a point where the science is lost.  Every little bit of knowledge adds to our understanding of ourselves.


© Michael Maglio

Wednesday, September 24, 2014

DNA Mysteries: Iberian R1b-V88 in Africa

   When I first heard about R1b in Africa, my immediate assumption was that the predominantly Celtic haplogroup must have been a recent transplant.  I ran some of the V88 haplotypes against the big databases (FTDNA & ySearch) expecting to see matches to European men within the African colonial timeframe.  It wasn’t that easy.  Common ancestor analysis put the R1b Africans (V88) thousands of years removed from the rest of their European R1b cousins.  Where did they come from?  How did they get there?


   I started with the given that the R1b defining mutations (SNPs) occurred in the Iberian Peninsula.  The jury is still out on this hypothesis.  There have been scientific papers for and against Iberian origins of R1b.  My own work (Iberian Origins of R1b) supports an origin prior to the Neolithic expansion.  Could V88 have made a straight-line migration from Iberia to the Lake Chad region of Africa?  Could V88 have crossed the Straits of Gibraltar, travelled across the Sahara, which 7,000 years ago was a savannah well populated with animals for hunting, and arrived at Lake Mega-Chad?  That was my early premise.  I was wrong.

   The distribution of V88 is much larger than any of the scientific papers would indicate.  While I agree with the work that’s been done correlating the spread of V88 with the spread of Chadic languages (Cruciani et al 2010), the Chadic population is only a subset.  Nobody takes into consideration the V88 populations in Europe and the Middle East.  If they do, it is a sideways glance to say were ignoring them because they don’t fit into what we are trying to prove.  If you don’t look at the entire picture, your conclusions will be skewed.

   I wanted the largest selection of V88 Y-DNA records with at least 37 markers tested.  I started with Family Tree DNA projects that had the records SNP tested.  Those haplotypes were run against the ySearch database to identify highly related records with no SNP testing.  The initial gathering of records picked up individuals with SNP M73.  These were removed.  The key differentiator between V88 and M73 was DYS464a&b.  V88 was typically 12,12 and M73 was 15,15.  Thirty-seven or more STR markers are helpful in identifying additional related haplotypes and even more necessary in determining the relationship between records.  Most studies only looks at SNPs or a small handful of STR markers.  This is shortsighted.  Imagine a reference population of 100 records all with the same SNP.  Without enough STR markers you can’t tell whether you are looking at one haplotype with minor 1 or 2 step variations or 100 unique haplotypes.  That’s the difference between a founder event starting with as few as one individual or a group with greater diversity and age.

   My final set of 119 records has at least 37 STR markers, V88 SNP testing or is highly related via STR and has the geographic location of the most distant known ancestor.  The records are processed through PHYLIP to generate a phylogenetic tree.  The phylogenetic tree give a visual depiction of the relationships in the dataset and an approximate number of years back to common ancestors, represented as the nodes between the records.


All of this is very standard genetic genealogy.  I add a twist (Biogeographical Multilateration) by converting the years back to a common ancestor to a distance using Cavalli-Sforza’s migration rate of 1 to 1.2 km per year.  This is enough for me to solve a series of cascading equations giving me the locations of the common ancestors.  Looking back at the phylogenetic tree shows us how all the nodes and locations are connected, essentially the flow of migration.


   The out of Iberia event took place about 7,700 ± 1,600 years ago.  TMRCA calculations have been shown to be very inconsistent.  Some folks use a constant mutation rate and some use rates per marker.  I include a TMRCA to give a relative chronology.  While the majority of R1b is known for its Western Atlantic migrations, V88 took a path along the Mediterranean coast and down the Adriatic.  While none of the V88 records indicated Crete as an ancestral location, it appears multiple times as a common ancestor location.  The data shows Crete as a stepping-stone in the Mediterranean as V88 migrated to the Nile River Valley.  The back to Africa event(s) occurred roughly 5,500 ± 1,000 years ago.


The majority of the Chadic records (Cameroon, Chad and Nigeria) have relatively close genetic connections to individuals in the Middle East (mainly Saudi Arabia).  The Chadic and Middle Eastern records tie back to common ancestors along the upper Nile.  There is a significant lack of information to understand what impact R1b-V88 had on the Nile Valley cultures.  Considering that there was only 1 out of 119 records with an exact Nile River location, I would venture a guess that V88 didn’t integrate well.

   While the V88 back to Africa migration has captured much attention, the data shows a more fascinating event.  There was a V88 re-migration back to Europe from Africa.   The back to Europe event took place about 3,200 ± 1,000 years ago.  Again, Crete played a role as a stepping-stone as V88 entered the Eastern Adriatic region and spread into Central and Eastern Europe.  Someone will probably notice that many of the V88 in Eastern Europe are Jewish and that the date for leaving the Nile region is close to the time of Exodus.  There is nothing in any of the data to indicate that this was the Jewish Exodus from Egypt.  The V88 group in Eastern Europe is closely related and there is phylogenetic evidence to support that this may have been a founder event with a single male or small group of closely related males.  There is no evidence to support that those founders were Jewish when they left Africa.


   By looking at the big picture, including all the data and letting the data illustrate the patterns, we can unravel what appears to be the mysterious appearance of R1b in Central Africa.  Along the way, we can uncover a previously unknown re-migration from Africa to Europe.  Too often haplogroup data is treated as discrete buckets of information living in a vacuum with no interaction to other haplogroups and no internal relationships.  Every DNA record is connected to every other record in a network.  Each haplotype is a vector with location and direction.  The sooner we treat genetic records as a network analysis, the sooner we will solve more DNA mysteries.

Out of Iberia and back to Africa.  Followed by a return to Europe.

Reference:

Maglio, MR (2014)  Y Chromosome Haplogroup R1b-V88: Biogeographical Evidence for an Iberian Origin (Link)


Thursday, February 20, 2014

Pushing the Boundaries

Tonight I made a guest appearance on Steve St. Clair's SinclairDNA BlogTalkRadio episode - Pushing the Boundaries of What Can Be Learned from Your DNA.


The episode was recorded live Friday, February 21 (2014).  You can listen to the recording through your computer by using this link - SinclairDNA

Steve and I talked about my recent experience with y-DNA research; Mapping y-DNA, William the Conqueror and a rare R1b group R-L11*.  We'll also talked a bit on the future of y-DNA testing.

Have a listen if you get a moment.  You can even download the show and take it with you.

Wednesday, January 29, 2014

Getting More from Your Genetic Testing Results: Y-DNA Mapping

   Y-DNA testing has only been around for about 15 years and can tell us about our direct paternal ancestry.  It is sometimes criticized for only being able to tell us about a small portion of our genetic history.  I think the critics forget that our mothers have fathers and there are a number of ways to obtain male test subjects to expand Y results across the entire family tree.  In the last few years, there has been a brighter spotlight on autosomal testing and its ability to test a larger portion of our genes.  This may have diverted research attention.  Relatively speaking, y-DNA is still in its infancy and there is much more to be learned.  In addition to our deep ancestral origins dating back over 10,000 years, we should be able to identify our old world homeland and our nomadic ancestor’s migration routes.  It is meaningful to know not only where they lived, but also when they lived to give us clues to their part in history.

   My closest genetic cousins and I share a common ancestor over 1,100 years ago.  With that many years between us, I didn’t spend a lot of time looking for a common surname.  For the last four years, I’ve been working with y-DNA to determine what can be learned beyond cousin matches and distant origins.  I originally tested with the Genographic Project and then transferred my results to Family Tree DNA for an upgrade.  In the time since getting my upgrade to 67 markers, I have received only one match.  This is due to my haplotype being somewhat rare and not a reflection of Family Tree DNA’s ability to provide matches.  I learned that I was part of haplogroup G, from the Caucasus Mountains.   I didn’t learn anything about how the ancestors of my Italian family traveled from Western Asia to Italy.
   I needed to find more cousin matches than the client base that had tested with FTDNA.  Ancestry.com allowed me to enter my y-DNA markers into their DNA section.  I compared my haplotype against the database at Sorenson Molecular (SMGF.org).  I also tried Genebase.com and any other place I could find.  I didn’t locate any cousins.  I did get a good education on what is out there for DNA companies and services.  FTDNA allowed me to transfer my results to Ysearch.org, a free public DNA matching service that they provide.  Ysearch provided much more flexibility.  Where FTDNA would only show me matches with a genetic distance of seven or less, Ysearch allowed me to select the genetic distance.  Without the genetic distance restrictions, Ysearch showed me hundreds of very distantly related cousins.  I’d rather have distant than none.  FTDNA is not trying to be difficult.  They are trying to be realistic and keep matches within genealogical timeframes.  I just needed more.
  While not used consistently, one of the best features of Ysearch is its ability to present the most distant known paternal ancestor (MDKPA) and their origin.  So now, I had cousins and their ancestral origins.  The greater the genetic distance, the closer I got to the Caucasus Mountains.  I mapped my closest cousins and their pushpins created a line from the Alps to the North Sea, directly along the Rhine River.  This was a pattern.  I like patterns.  There is usually a scientific reason for a pattern.

Figure 1 – Mapping Ancestral Origins

   I’ve run a few hundred genetic mapping exercises on the majority of Y haplogroups.  The patterns are consistent.  Our ancestors traveled along rivers and coastlines.  They skirted mountain ranges and crossed bodies of water.  There is always a flow to the patterns, but the science and the why were still missing.  I’ve always been interested in early Eurasian history and have tried to associate it to the patterns in the maps that I generated.  Some maps have places and dates that connect well to notable events.  Other maps raise more questions than answers.  Genetic tests and history alone were not making a complete picture.  I needed to add population genetics, migration models, anthropology and evolutionary biology to my knowledge base.
   Take any  two people on the planet, compare their DNA and you can calculate, approximately, how far back in time their common ancestor lived – time to most recent common ancestor (TMRCA).  Our ancestors were nomadic and traveled about 25 to 30 km per generation or roughly 1 km/year on average.  If a common ancestor lived 300 years ago, then that person’s descendants may have migrated 300 km from the geographic origin of that ancestor.  In the figure below, d1 and d2 represent the origins of two known y-DNA genetic records.  The circles show the distance their ancestors may have migrated.  The intersections are the potential locations of their common ancestor.  In this case, there are two intersections, a1 and a2.  More y-DNA records are required to figure out which intersection is correct.

Figure 2 – Distance to Most Recent Common Ancestor (Bilateration)

   The genetic analysis that I have developed is similar to a navigation technique.  Radio navigation uses two or more beacons with known locations and a measurement of the time it takes to receive a signal from each.  The time is converted to a distance.  A current location can then be identified.  In my method, the “beacons” are the ancestral geographic origins. The “signal” is the TMRCA, measured in years, converted to a distance by multiplying the average migration rate – creating a distance to most recent common ancestor (DMRCA).  A location for the common ancestor can then be figured out by looking at the intersections.  Multiple y-DNA records are needed to determine migration direction and geographic origins of a related set of genetic cousins.  The science is starting to take shape.
  I am G-Z726, which is a subgroup of G-Z725.  At Ysearch or on an FTDNA project you may still see an older naming convention - G2a3b.  As an example, let’s look at 18 of my closest genetic cousins – haplogroup G-Z725, (DYS388=13).  TMRCA data is generated using Dean McGee’s Y-Utility.  The output is turned into a phylogenetic tree and the DMRCA is calculated. 

Figure 3 - Phylogenetic Tree - G-Z725 Sample

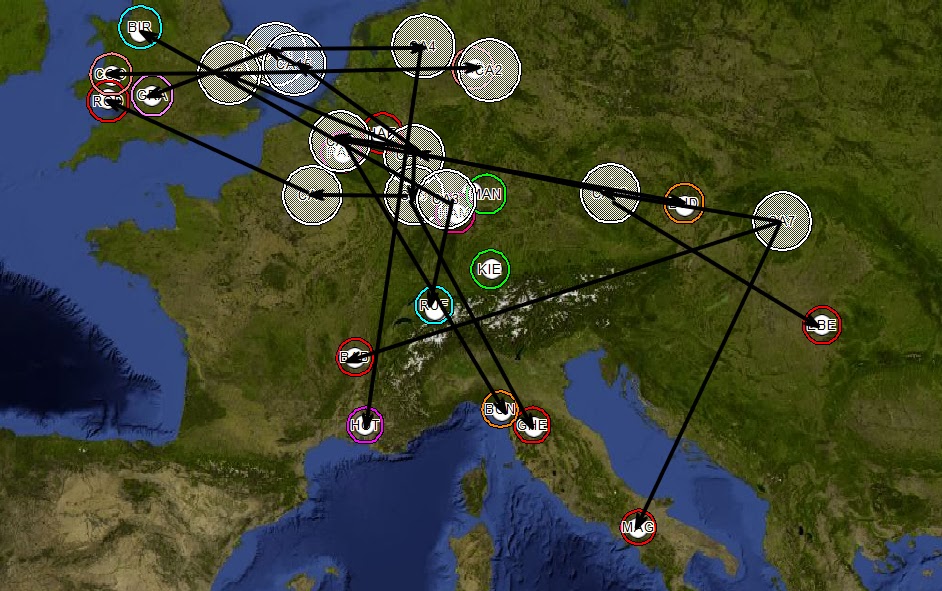
Each distance is used to draw a circle that represents the migration range of that ancestral line.  My range (MAG) and the range of my next closest cousin on the tree (BAB) create two intersections on the map.  One point is in Africa and the other is in Eastern Europe.  

Figure 4 - Intersection of MAG and BAB

By adding the range of cousin EBE, the correct intersection representing common ancestor 7 (CA7) is identified.  Pairs of records are mapped to continue the analysis.

Figure 5 - Intersection of BIR and RUF

BIR and RUF are another example and they identify common ancestor CA3.  Each record is added until all common ancestors are identified. 

Figure 6 - Common Ancestors Mapped

Connections are drawn based on the phylogenetic tree.

Figure 7 - Phylogenetic Tree Superimposed

Then for simplification, the migration flow is generalized.  Based on the phylogenetic analysis, common ancestor 7 (CA7) is the most distant common ancestor (MDCA) of samples in this example.  The western migration flow has a slight correlation to the Danube River and the North/South migrations have a strong correlation to the Rhine River.  Early attempts at direct mapping of genetic data (Fig. 1) gave similar results based on TMRCA alone.  There was no corroborating evidence of directionality or definitive proof of MDCA.  

Figure 8 - Generalized Migration Flow - G-Z725

   The new methodology that I have developed shows ancestral origins and migration direction.  I call this method biogeographical multilateration (BGM).  It is the geographical distribution of y-DNA data based on multiple distance measurements from reference positions. 
   This method also has the potential to identify the location of a DNA sample when the origin is unknown. For one of my clients, I identified that his paternal ancestor that had immigrated to the United States may have anglicized their name.  The previous name was German and that surname was found predominantly in central Germany.  Applying biogeographical multilateration to my client’s y-DNA results, while leaving the origin as an unknown, indicated a continental European origin within 200km of the city with the highest surname density.
   In the referenced paper, the example haplogroup, I-L22, has an approximate correlation to the Norse/Viking invasions of Britain and identifies a Frisian coast staging area.

Figure 9 - Generalized Migration Flow - I-L22

  We are still in the infancy of what we can learn from y-DNA.  My BGM analysis has room for refinement.  There is enough science out there to help us.  New research is being done at the aggregate population level.  We can apply elements of that research to the individual level.  Biogeographical multilateration has the potential to fill the gap in our knowledge between genealogical records and deep haplogroup roots.  This new tool can give us old world ancestral origins, migration flow and historical timeframes.
   I needed to learn more about my DNA and my origins.  The big testing companies haven’t filled the knowledge gaps that exist.  They are in the business of providing quality test results.  The analysis and tool creation is falling on the shoulders of “citizen scientists”.  Sometimes, you just have to do it yourself.

Reference:

Maglio, MR (2014)  Y-Chromosome Haplotype Origins via Biogeographical Multilateration (Link)

Tuesday, November 20, 2012

Stephen Hopkins: Saxon DNA?


   As we approach Thanksgiving, it’s a great time to write about our Mayflower ancestors.  So far, I have found two on my wife's side, Stephen Hopkins and Stephen Hopkins.  Ok, that’s really just one, but I have two lines that trace back to him.   This isn’t unusual, estimates put the count of Stephen Hopkins’ descendants at about 2 million Americans.  

   What can Stephen Hopkins’ DNA tell us about his origins and his ancestors?  First, I should say that no one has a sample of Stephen’s DNA.  What we know about Stephen comes from tests completed by his male-line descendants with corroborating genealogical paper trails.  The Hopkins families are members of y-DNA haplogroup R1b, the largest genetic population in Europe.  R1b is often associated with the Celtic and Gallic tribes.  Hopkins’ DNA may be able to shed additional light on his birthplace, extend his genealogy further by tapping into an older family line or tell us about his deep ancestral origins.

   One of the first things I like to do is compare the haplotype, (the numeric markers from a y-DNA test) against a public database like ySearch.org.  The goal is to find other parallel lines of Hopkins with ancestry that predates Stephen.  This would allow us to work forward in time, connecting to Stephen and his father John, breaking through the current brick wall.  Unfortunately, no such records exist.

   What we do get from ySearch is list of genetic cousins and their ancestral locations.  Plotting these locations generates a distribution from Kent to Cornwall across southern England.  The highest concentration of cousins is in the historic Anglo-Saxon kingdom of Wessex.  The current research on Stephen Hopkins has him baptized in Hampshire, the heart of Wessex.
 
   What kind of R1b was Hopkins?  Was he a Celt, a Gaul, an Anglo-Saxon or something completely different?  One way to get close to the answer is to look at his genetic cousins again.  Since R1b is such a large group, it is important to focus on both the haplotype and SNP that defines his R1b subgroup.  The SNP that best defines Stephen is S493, which on the 2012 haplogroup tree is R1b1a2a1a1a2.  With the explosion of new SNPs identification and the rapidly expanding and changing subgroup nomenclature, researchers are advocating the use of the SNP rather than subgroup as a naming convention.  Let’s call Stephen Hopkins R-S493.

   When I take all these genetic cousins and run them through TribeMapper®, a pattern forms.  Ancestors start to pile up on either side of the English Channel and an approximate date of migration emerges.  Here’s where we pull out our history books.  If the date were about 2,500 years ago, I would say this was a Celtic migration.  If the date were 2,000 years ago, I might say these were Gaels fleeing the Romans.   The calculations come out to be about 1,500 years ago, putting this migration in line with the Anglo-Saxon invasion of Britain.

   Why stop there?  What flavor of Anglo-Saxon are we talking about?  Angle, Saxon, Jute?  The great thing about tribe mapping is that we can continuously turn back the clock and get a new picture.  If we find a Danish connection, then we might say Jutes or an association to the Angeln region of Germany, we could say Angles.  We have to be careful as those names and locations were just a snapshot in time when ancient historians catalogued Germanic tribes.  Those tribes, like all tribes, were just passing through.

   Stephen Hopkins’ DNA points to a genetic cluster in modern day Lithuania and Latvia.   This data most closely correlates to the Saxons and their origins on the Baltic coast.  Continuing this process gives us the following migration map.


   The R-S493 data takes us through Finland, Sweden and back to the mainland Europe to the Iberian Peninsula.  This puts the origin of R-S493 in Iberia about 4,000 years ago ± 500 years.

   We can’t be certain that Stephen Hopkins has Saxon DNA.  We can’t even say that all Saxons were haplogroup R1b.  It’s unlikely that they were a single homogenous ethnic group, but the core of the tribe would have had strong familial and genetic ties.  Were Hopkins’ ancestors at the core of this tribe or part of the fringe, picked up along the way?  A broader study of DNA associated with the same places and times would be required to answer that question.

   If we look at the surname Hopkins, its origins are from Hobbes-kin and even further back to the Germanic name Hrodberht.  Stephen Hopkins and his closest genetic cousins are found in the historic Kingdom of Wessex (West Saxons).  Time-wise, there is a correlation to the Anglo-Saxon invasion of Britain.  We can even make a connection to the proto-Saxons along the Baltic coast.  I’m going out on a limb and calling Hopkins a Saxon.

   That Saxon bloodline remained adventurous and served Stephen well as he voyaged to Bermuda, Jamestown and Plymouth colony.

   It’s never obvious where DNA will lead.  Each tribe mapping is an adventure in itself.


© Michael R. Maglio and OriginsDNA

Friday, September 7, 2012

Your Father's Father


Deep Into DNA*


   Raise your hand if you’d like to know more about your surname and your father’s ancestry.  I’m raising mine!

   Most of us live in a patrilineal society.  The wife and the children take the surname of the husband.  We can’t help but to associate with our father’s family, his clan.  The males in the family will inherit the Y chromosome virtually unchanged, though genetically, we can only attribute a small fraction of our overall DNA to that patrilineal line.  Psychologically though, 50% of our ethnic identity comes from dad.   


   We have all tried traditional genealogy for our father’s line.  Some of us go back a couple of generations and some of us have researched a dozen generations.  A few of us are adopted and know nothing about our paternity.  Y-DNA testing has benefits that aid a genealogist in all these situations...

...continued at The In-Depth Genealogist with a free membership.

*The Deep Into DNA article series is published each month in The In-Depth Genealogist Newsletter and will demystify genetic genealogy and make sense out of DNA testing terminology.  Each month we will talk about the types of tests available from major labs and show relevant examples on how to use DNA in your genealogy research.

#gDNA

Tuesday, March 20, 2012

TMRCA: DNA and the 4th Dimension

Time to Most Recent Common Ancestor


TMRCA answers the question, ‘OK, you and I are related. How far back in time do we have to go to find the connection?’


Take any two organisms, two mushrooms, two rabbits or two humans and compare their DNA. If you know how the DNA is different and you know the rate of mutation for the differences then you can calculate how far back in time they have a common ancestor.

In this mini-webinar I will explore how close or distantly in time various DNA tests will take you and various tools for calculating and visualizing TMRCA data.

You can find the webinar on my YouTube page.

#gDNA

Thursday, March 15, 2012

Mapping Your Tribe


If I asked you where your ancestors were last year or 100 years ago, you could probably tell me.  If you have a yDNA or mtDNA test in your hands, you could tell me where your ancestors were 30,000 years ago.


Where were your ancestors 1000 or 2000 years ago?  What events did they witness?  What history did they make?

Join me as we combine DNA and history to Map Your Tribe.

Tuesday, March 27th at 7pm
22 Elm St, Gardner MA – American Legion Post #129

Where did you come from? 

#gDNA